Critical equipment does not always fail without warning. Sometimes the warning signs already exist in electrical readings, operating patterns or other equipment data. The bigger problem is that the information is not visible to the right people at the right time.
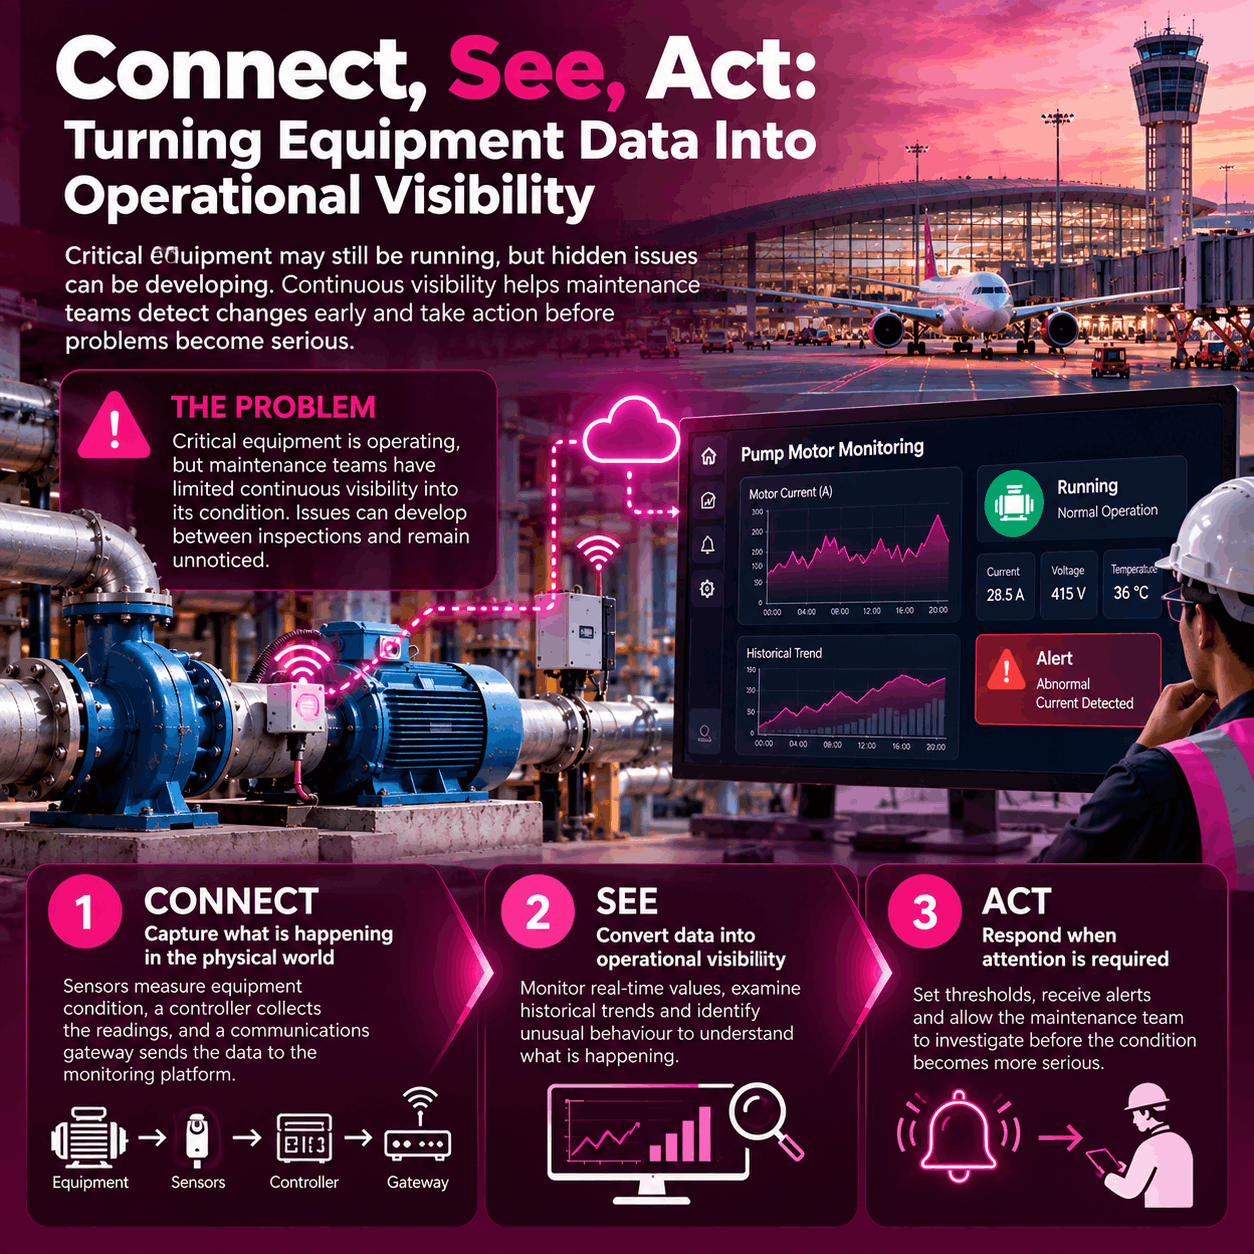
An airport water pump monitoring project illustrates this challenge. The objective was not simply to put sensors on pumps or send data to the cloud. The operational requirement was to give maintenance personnel continuous visibility into how the equipment was behaving.
The Problem: Critical Equipment With Limited Visibility
Traditional equipment monitoring can depend heavily on local systems, periodic inspections and technicians visiting the site. While these methods remain part of maintenance operations, they leave gaps between inspections.
During those gaps, equipment behaviour can change. A motor may draw more current than usual, experience an unexpected drop or begin developing an unusual operating pattern. Unless somebody sees that change, the condition may remain unnoticed until the next inspection or until a larger problem develops.
The problem statement can therefore be expressed simply: How can an organisation continuously understand what is happening to critical equipment without requiring someone to be physically present?
The answer can be structured around three operational stages: Connect → See → Act.
CONNECT: Capture What Is Happening in the Physical World
Sensors collect information about the operating condition of the equipment. An industrial controller gathers those readings and an industrial communications gateway sends the information to a remote monitoring platform.
The result is a continuous digital connection between physical assets and the people responsible for them. Equipment that previously required local observation can now communicate its condition remotely.
SEE: Convert Data Into Something People Can Understand
Connectivity creates data, but operational teams need visibility. A monitoring platform can present current readings, historical trends and equipment behaviour in a form that allows engineers and maintenance personnel to understand what is happening.
Instead of asking only whether a pump is running, the team can ask whether it is operating normally, whether its behaviour has changed and whether that change requires investigation.
This is where IoT moves beyond connectivity. The objective is not simply to collect more data. The objective is to reduce uncertainty about what is happening across operations.
ACT: Respond When Attention Is Required
The final stage connects visibility with human action. Thresholds and rules can identify conditions that require attention and generate alerts for responsible personnel. The maintenance team can then investigate the equipment rather than waiting for a routine inspection or an obvious failure.
This creates a continuous operational loop where the physical and digital worlds support each other:
Connect the assets that matter, see what is happening across operations, and act when the information indicates that intervention is required.
For organisations considering IoT, the starting question should therefore not be, “Which IoT technology should we buy?” A more useful question is: “What is happening in our operations today that we cannot see until someone physically checks it or something goes wrong?”
Once that blind spot is clearly defined, the role of IoT becomes much easier to understand. The technology is no longer the centre of the story. The operational problem is.
[Note: This is one of Favoriot‘s Commercial Use Case – Pump Monitoring]
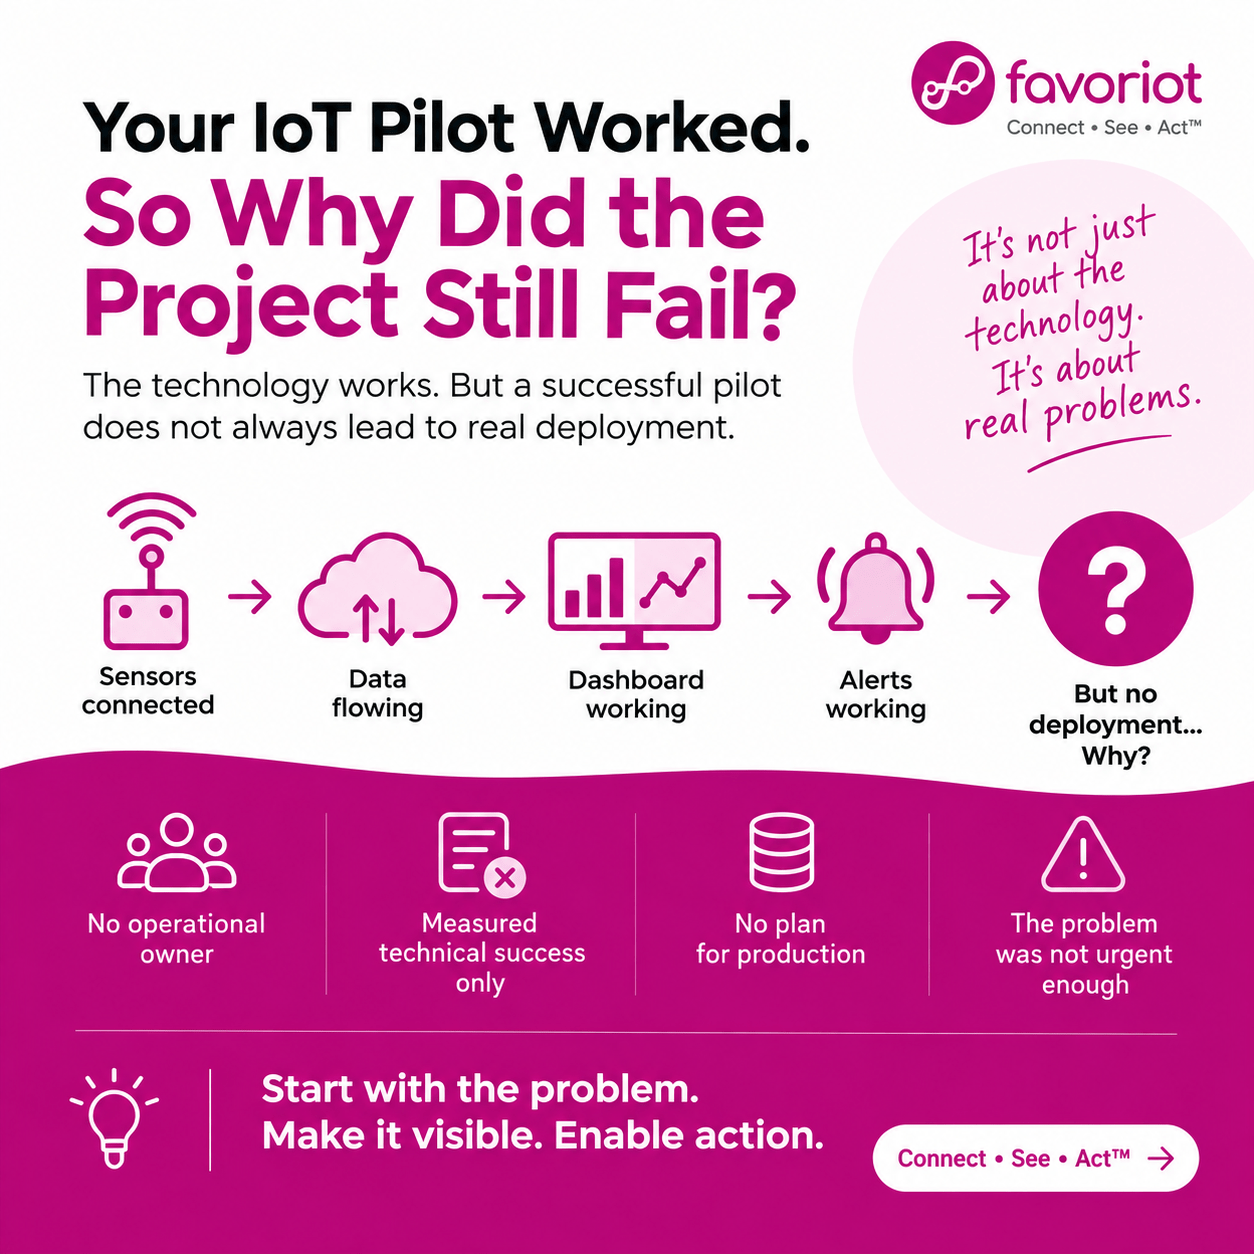
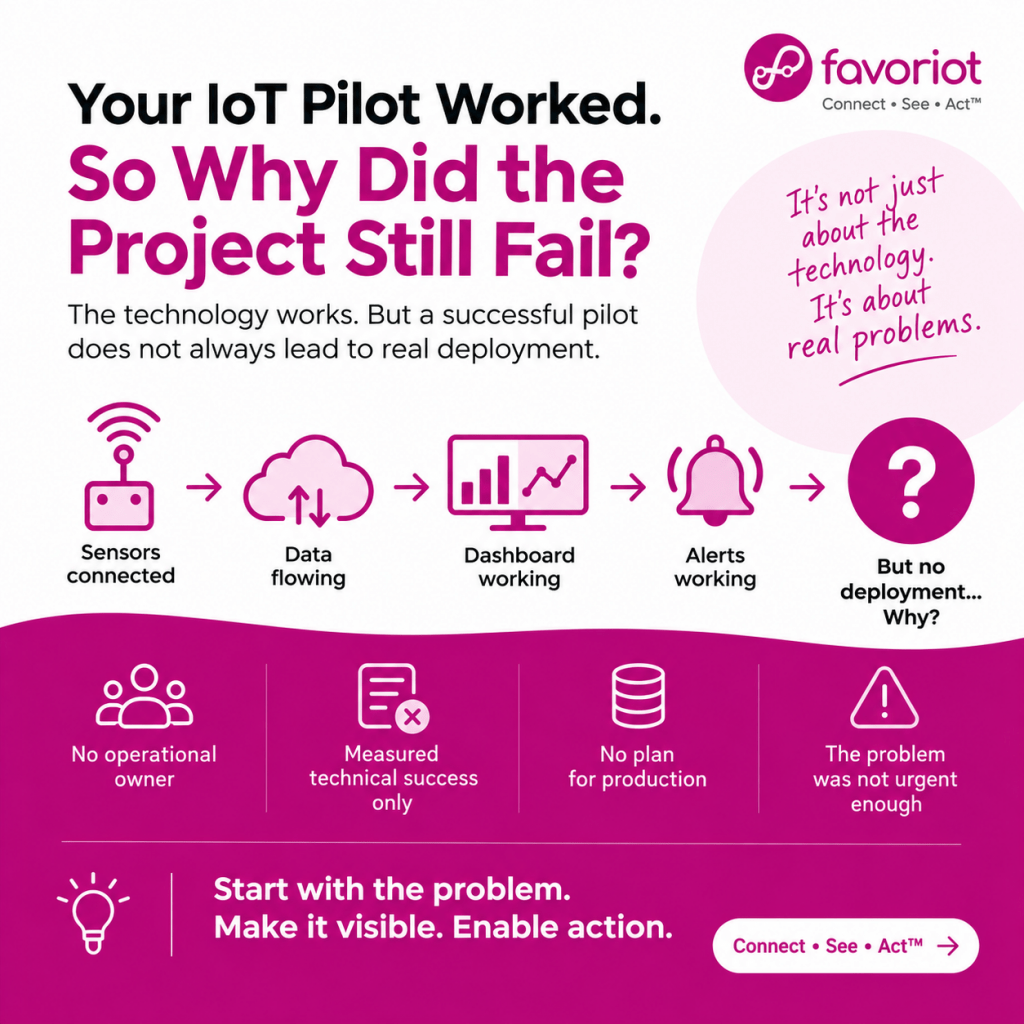
The sensors are connected, data is reaching the cloud, dashboards are displaying information correctly and alerts are being generated. From a technical perspective, the IoT pilot has achieved what it was designed to demonstrate.
Yet this is often the point where the harder part begins.
At FAVORIOT, our experience working with IoT projects has taught us that proving a technology works does not automatically create a reason for an organisation to deploy it across more assets, sites or facilities. A technically successful pilot can still stop because the project has not demonstrated enough operational value to justify what comes next.
This distinction has changed how we believe IoT projects should be approached.
IoT Has Become Much Easier to Build
There was a time when organisations needed considerable technical knowledge just to experiment with IoT. Connecting sensors, configuring communication protocols, sending data to a cloud platform and creating dashboards required specialised skills.
That barrier has fallen considerably. Hardware such as ESP32 and Raspberry Pi is widely available, IoT platforms simplify device connectivity, and developers have access to extensive documentation and examples. Generative AI has lowered the learning barrier further by helping users generate code, troubleshoot errors and understand technical concepts.
Building an IoT prototype is no longer the biggest challenge for many organisations. The more difficult challenge is turning that prototype into something people depend on every day.
The Problem With Starting From Technology
Many IoT projects begin with a technology question: “Can we connect this equipment?”
There is nothing wrong with testing technical feasibility. The problem appears when connectivity becomes the primary measure of success. A pilot may demonstrate that sensors can collect data, MQTT can transport it and a platform can display it, but none of these automatically demonstrates operational value.
A stronger starting point is to ask what the organisation currently cannot see.
Perhaps maintenance teams do not know that a remote pump has stopped until someone visits the site. A facilities manager may not notice abnormal electricity consumption quickly enough. An environmental team may receive information too late to respond effectively, while operators managing remote assets may spend considerable time travelling to locations simply to check whether equipment is functioning.
These are operational problems. IoT is the mechanism for making them visible.
A Pilot Needs an Operational Owner
One of the most important questions should therefore be asked before the pilot begins: Who owns the operational problem?
An IT department may support connectivity and cybersecurity, while an engineering team manages equipment and another department controls the project budget. If nobody has responsibility for the outcome the IoT system is supposed to improve, moving beyond the pilot can become difficult.
The operational owner should be able to explain why the problem matters, what happens when it is not detected early and what action should follow when the IoT system identifies an abnormal condition.
This also changes how pilot success should be measured. Instead of measuring only whether devices connected successfully, organisations can measure whether the project reduced unnecessary site visits, shortened response times, detected problems earlier, reduced downtime or provided better visibility into energy and resource consumption.
The Dashboard Should Not Be the Destination
Dashboards have become almost synonymous with IoT, but a beautiful dashboard does not automatically mean that an organisation has improved its operations.
The more useful question is what happens after someone sees the information.
If a temperature exceeds a threshold, who receives the alert? If equipment suddenly stops, who investigates? If energy consumption becomes abnormal, what action follows? If environmental conditions deteriorate, how quickly can someone respond?
This is the thinking behind FAVORIOT’s Connect → See → Act™ approach. Connecting an asset provides data. Making that information visible creates awareness. Acting on the information is where operational value begins.
Five Questions to Ask Before Starting an IoT Pilot
Before investing in another proof of concept, organisations should be able to answer five practical questions:
What operational problem are we trying to solve? Define the problem before selecting sensors, devices or platforms.
What can we not see today? Identify the missing information that prevents faster or better decisions.
Who owns this problem? There should be someone responsible for the operational outcome, not merely the technology.
How will we measure success? Include operational measures such as response time, downtime, site visits, losses or resource consumption.
What happens if the pilot succeeds? Consider production deployment, support, maintenance, connectivity, cybersecurity, budgets and responsibilities before reaching the end of the pilot.
These questions may appear less interesting than discussing sensors, protocols or dashboards, but answering them early can determine whether an IoT project becomes part of daily operations or ends as another demonstration.
From Proof of Technology to Operational Visibility
The IoT industry has spent years proving that connected technology works. We no longer need every project to begin by proving that a sensor can communicate with the cloud. The bigger opportunity is proving that better visibility can improve how an organisation operates.
This is also why FAVORIOT increasingly approaches IoT through the lens of Operational Visibility. The objective is not simply to connect more devices. It is to help organisations see what is happening across physical assets, equipment and environments early enough for people to make better operational decisions.
Before asking “Which sensor should we use?” or “Which IoT platform should we choose?”, there is a more important conversation to have: What operational problem are we trying to make visible, who owns that problem, and what action should happen when we see it?
A pilot that answers those questions has a much stronger reason to continue beyond the demonstration stage. The goal is no longer simply to prove that IoT works. It is to make sure that when the technology works, something meaningful happens because of it.
Most organizations never calculate what their blind spots actually cost them. Delays, uncertainty, repeated failures, manual checking, rework, energy waste, missed alerts, and poor reporting all get accepted as normal operating friction. Nobody puts a number on it because nobody is asked to.
This is the single biggest reason visibility projects stall at the budget stage. Without a number, a proposal to close a blind spot competes against every other line item as a nice-to-have. With a number, it becomes a comparison: the cost of staying blind versus the cost of seeing clearly. That comparison is what moves a project from “interesting” to “approved.”
This article walks through how to estimate the cost of a blind spot in a way that is defensible, fast enough to use in early discovery, and credible enough to bring to an executive.
Why the cost of blindness is rarely calculated
Operational blindness is invisible by definition. When a machine fails without warning, the organization sees the repair bill, not the six weeks of undetected wear that preceded it. When a report takes three days to compile manually, the organization sees the report, not the labor hours buried inside it. The cost is real, but it is scattered across departments, absorbed into “the way things are,” and rarely tied back to the missing visibility that caused it.
The estimate does not need to be perfect. In early discovery, it needs to be clear enough to show whether the problem deserves attention at all. A rough number that says “this blind spot is costing roughly RM 40,000 a month” is more useful than a precise number that takes three months to produce.
The six cost areas to check
Blind spots rarely cost money in only one way. Before estimating, work through these six areas and ask which ones apply to the specific blind spot in front of you.
Downtime. How many hours are lost per month because a failure or deviation was detected late instead of early? This is usually the most visible cost and the easiest to find in maintenance logs, production records, and incident reports.
Energy waste. Which assets consume energy without producing business value, because nobody can see they are running idle, overcooling, or malfunctioning? Meter data, equipment schedules, and occupancy records usually hold the answer.
Manual work. How many staff hours go into checking, copying, or reconciling data that should already be visible? Look at the report process itself, who owns each step, and how long the spreadsheet trail has been in place.
Compliance risk. Which metrics are hard to prove during an audit because the underlying data was never captured automatically? Regulatory reports, source records, and exception files reveal where the gaps sit.
Response delay. How long passes between an event happening and someone acting on it? Alert logs, communication records, and workflow timestamps show the real lag, which is usually longer than anyone assumes.
Customer impact. Which visibility gaps show up in complaints, missed service levels, or support tickets? This is the cost area most likely to be underestimated, because it shows up as churn and reputation damage rather than a line item.
A single blind spot can touch more than one of these areas at once. A missed maintenance alert, for example, carries downtime cost, energy waste, and customer impact together. Estimating each area separately and then adding them keeps the final number honest instead of inflated.
A simple estimation method
For each cost area that applies, work through three questions.
First, how often does the blind spot occur. A weekly event and a quarterly event carry very different annualized costs, so get a real frequency, not an impression.
Second, what is the cost per occurrence. This can be a repair bill, a headcount hour rate multiplied by hours lost, a wasted kilowatt-hour rate, or an estimated revenue impact per incident. Where a hard number does not exist, use a conservative range rather than skipping the category.
Third, multiply frequency by cost per occurrence to get an annualized figure for that area, then sum across all applicable areas.
This produces a defensible range, not a single decimal-point figure, and a range is exactly what is needed at this stage. Precision comes later, once instrumentation is in place and the numbers can be measured directly instead of estimated.
Where to get the evidence
Estimates built on guesses do not survive a conversation with finance. Each cost area has a natural evidence trail already sitting inside the organization.
Downtime numbers live in maintenance logs, production records, and incident reports. Energy waste shows up in meter data, equipment schedules, and occupancy records. Manual work is documented, even informally, in the report process itself, staff roles, and spreadsheet history. Compliance risk is visible in regulatory reports, source records, and exception files. Response delay is timestamped in alert logs, communication records, and workflow systems. Customer impact is already tracked in complaints, SLA records, and service tickets.
Asking for recent, specific examples produces better numbers than asking for general opinions. What happened last week. Which asset failed most recently. Which report arrived late. Which alert was missed. Which customer complained. Recent stories carry texture that a broad estimate cannot, and they anchor the cost calculation to something real rather than theoretical.
Turning the number into a decision
Once the cost of blindness is visible, the conversation changes shape. The project stops being a request to buy a platform or add sensors, and becomes an investment case to reduce a specific, quantified risk or capture a specific, quantified opportunity.
The comparison that matters is simple: the cost of building visibility against the cost of remaining blind. If closing a blind spot costs less than what the blindness is already costing every year, the case makes itself. If it costs more, that is useful information too. It tells the team to look for a smaller blind spot with a clearer payback, or to combine several blind spots into one investment that clears the bar together.
This is also why the estimate belongs early in the discovery process, not at the end. It shapes which blind spots get prioritized, which stakeholders need to be in the room, and how the eventual proposal gets framed. A proposal built around a quantified cost of blindness reads as consultative rather than product-led. The organization sees its own problem reflected back with a number attached, and the number is what makes the next conversation, about budget, easy instead of speculative.
The habit worth building
The organizations that manage this well do not treat cost-of-blindness estimation as a one-time exercise before a project starts. They build it into how they evaluate every operational gap that surfaces afterward. Every missed alert, every delayed report, every manual reconciliation becomes a small case study, and over time the organization develops a working library of what blindness actually costs across its operations.
That library is worth more than any single estimate. It turns “we think this matters” into “here is what it has cost us before,” and that shift, from intuition to evidence, is what separates organizations that fund visibility projects from organizations that keep accepting friction as normal.
Cost of Blindness Calculator | FOBA
FOBA · Find Phase Tool
Cost of Blindness Calculator
Operational blindness has a cost, but most organizations never calculate it. Estimate what a blind spot is really costing across six areas, then compare it against the cost of closing it.
Estimated annual cost of blindness
RM 0
RM 0 / month
Cost areas active
0 / 6
areas with a non-zero estimate
Largest contributor
—
no data yet
Annual cost by area
Visibility investment comparison
The cost of visibility should be compared against the cost of remaining blind. Enter the estimated cost of the project that would close this blind spot.
VS
Enter a project cost to compare it against the estimated cost of blindness.